Why teaching a machine to speak Thai is harder than it sounds
Five tones, no spaces between words, and a script that hides its own pronunciation — a tour of the problems behind Thai text-to-speech.
BOTNOi Voice Team
2 min read · Oct 28, 2026
Five tones, no spaces between words, and a script that hides its own pronunciation — a tour of the problems behind Thai text-to-speech.
Type a sentence into any English text-to-speech engine and it will usually get the words right. The rhythm might be flat, but you will understand it. Try the same with Thai and the cracks show almost immediately.
That gap is the reason BOTNOI started working on voice in the first place. If you want a machine to talk to people in Thailand, "almost right" is not good enough. A wrong tone does not sound like an accent. It sounds like a different word.
Written Thai does not put spaces between words. Spaces mark the end of a phrase or sentence, roughly where English would use a comma or a full stop. Before a speech engine can pronounce anything, it has to decide where each word begins and ends.
That sounds like a solved problem until you meet ambiguous strings, which can be split in more than one valid way and mean different things depending on the split. Names, brand names and English loanwords written in Thai script make it worse, because they are often not in any dictionary.
A wrong tone does not sound like an accent. It sounds like a different word.
Thai has five lexical tones: mid, low, falling, high and rising. The tone of a syllable is not always written as a single mark. It comes from a combination of the consonant class, the tone mark (if there is one), whether the vowel is long or short, and how the syllable ends.
A good voice model has to learn those rules, and the long list of exceptions that come with real-world spelling. Get it wrong and a polite sentence can turn into something confusing, or funny for the wrong reasons.
Real text is messy. A customer-service script will contain phone numbers, dates in the Buddhist calendar, prices with "บาท", English product names, abbreviations and emoji. Before any audio is generated, all of that has to be normalized into words a person would actually say out loud.
This step, usually called text normalization, is unglamorous and decides a lot of the final quality. "2569" should be read as a year in one sentence and as a quantity in another.
Once the words and tones are right, the remaining work is what makes a voice pleasant to listen to: natural pauses, emphasis, and a speaking pace that fits the context. A voice reading an audiobook should sound different from one confirming a hospital appointment.
Modern neural TTS learns much of this from data, which is why the quality and variety of recorded speech matters as much as the model architecture.
Voice is the most natural interface most people have. For a Thai bank, hospital or shop, a voicebot that speaks clear, natural Thai can answer the phone at 2 a.m. and sound like it belongs there.
That is the bar we hold ourselves to: not a machine that can read Thai, but one that people are comfortable listening to.
Voice AI is rapidly shifting from robotic text-to-speech engines into fluid, real-time conversational systems. Here is why speech is emerging as the primary interface for the next generation of AI.
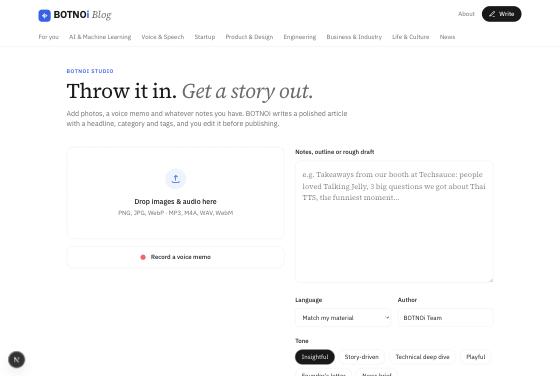
BOTNOI Blog เปิดตัวพร้อมเครื่องมือเขียนบทความที่ช่วยเปลี่ยน Voice Memo และรูปถ่ายดิบๆ ให้กลายเป็นเรื่องเล่าคุณภาพ เพราะหน้าที่ของ AI คือการทลายหน้ากระดาษว่างเปล่า ไม่ใช่การแทนที่เสียงของมนุษย์
ยินดีต้อนรับสู่ BOTNOI Blog พื้นที่รวบรวมเรื่องราว อัปเดตข่าวสาร และมุมมองเชิงลึกด้าน AI เทคโนโลยี และการขับเคลื่อนธุรกิจด้วยปัญญาประดิษฐ์